SwarmInfer: Decentralized LLM Inference Across Consumer GPUs
The Problem
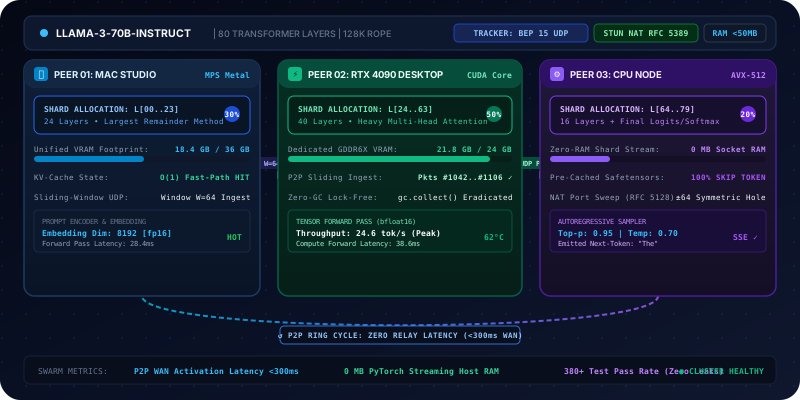
Running distributed 70B+ LLM inference across untrusted consumer hardware without central relay bottlenecks, prohibitive coordinator RAM overhead, or brittle socket drops.
The Architecture
Engineered a custom sliding-window UDP transport layer with STUN/ICE hole punching, zero-copy disk shard streaming, and dynamic latency routing. Validated across 380+ adversarial drop tests with sub-50 MB coordinator footprint.